We spend a lot of energy arguing about whether AI is actually intelligent. A model produces a useful explanation, and the discussion quickly turns to whether it understands what it has said. Is there reasoning behind the answer? How much comes from patterns learned during training?
These are serious questions. But when I think about how engineers should work with AI, I find it useful to separate the scientific question from the immediate management decision.
We do not need a final verdict on whether AI has human-like intelligence before evaluating its practical value. We do need to establish what a particular system can do and how its output will be checked. For engineering work, intelligence amplification is a useful frame: judge whether people working with the technology reach a better understanding and make better decisions.
Knowing a great deal and adapting successfully to an unfamiliar situation are different accomplishments. Consciousness raises another question altogether. We should be careful about treating a convincing conversation as evidence that all three have been established.
In a paper, On the Measure of Intelligence, François Chollet proposes assessing intelligence through how efficiently a system acquires new skills, taking account of its prior knowledge and experience. Under that definition, impressive performance on a familiar task does not, by itself, establish broad intelligence.
Other interpretations put more weight on demonstrated capabilities. A 2023 PNAS perspective by Melanie Mitchell and David Krakauer examines competing views on whether language models understand what they process, including the possibility of forms of understanding that differ from our own. The debate concerns what the performance means, as well as the performance itself.
I would keep the word intelligence available, provided we say what we mean by it. A system might demonstrate a capability we reasonably describe as intelligent without giving us grounds to treat it as a human expert. The definition should sharpen the evaluation rather than substitute for it.
I understand the appeal of describing AI as a knowledge base on steroids. It captures something important about the experience: you can explore an unfamiliar subject through a conversation instead of beginning with whatever you already know to search for.
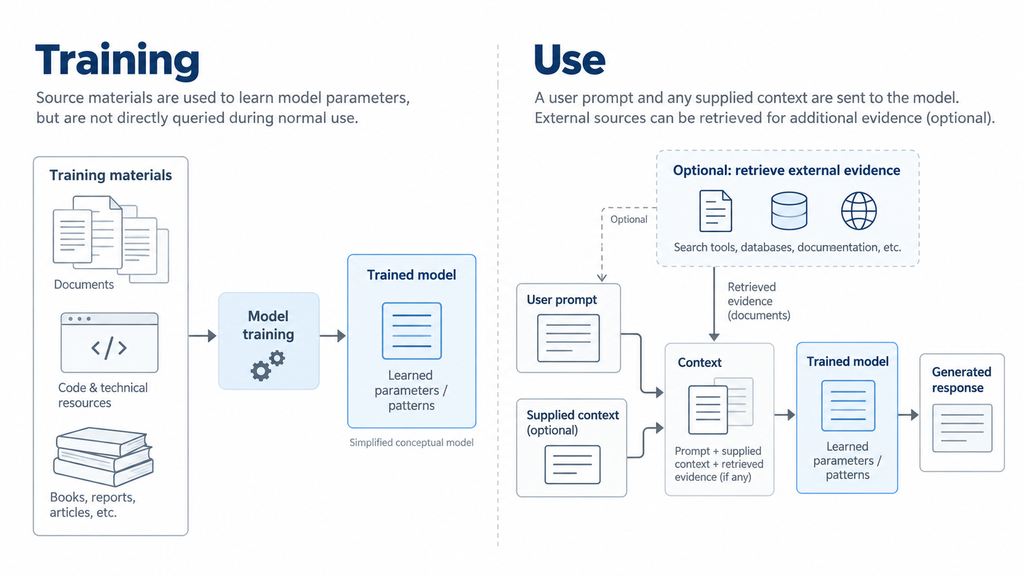
The metaphor becomes less useful when taken literally. A language model learns numerical parameters from training data and uses those learned relationships to generate responses. It is not a complete, searchable catalogue of everything it encountered. Models can also memorize and reproduce some training material, so the distinction is more nuanced than saying they never retain anything.
Access to external documents is a separate capability. In retrieval-augmented generation (RAG), a system retrieves material and uses it to inform its response. Retrieved material can give the user sources to inspect, but it does not establish that the answer correctly represents those sources. Learned information and retrieved evidence should remain distinguishable.
Calling the model a predictor also leaves part of the practical question unanswered. The 2020 GPT-3 research demonstrated performance on tasks specified through instructions or examples in a prompt, without updating the model for each task. A training objective tells us something about how a capability develops; evaluating the resulting capability still requires testing.
For an engineer, the useful working assumption is that the system can offer more than stored quotations, while every important claim still needs an evidential basis. Neither a fluent explanation nor a familiar technical term tells you whether the proposed mechanism applies to your process.
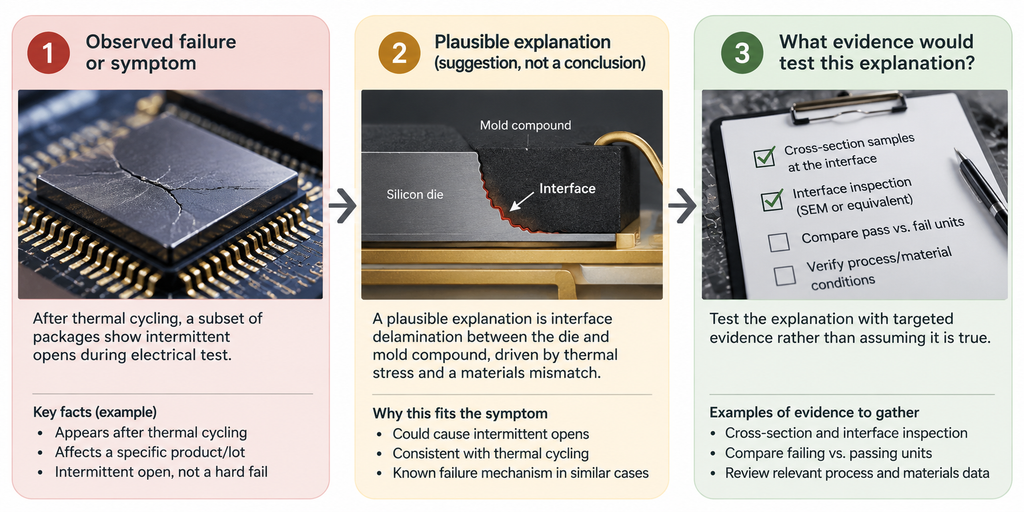
Consider a hypothetical packaging investigation. A reliability engineer is examining intermittent failures after thermal cycling. The team has concentrated on bonding settings. During a discussion using approved technical context, an AI assistant suggests examining whether an earlier surface-preparation step could be affecting the interface.
For this example, assume the suggestion is technically plausible but unverified. Its immediate value is that it opens a question the team had not been pursuing. The engineer can now ask what process history would support the explanation and whether comparable, unaffected material contradicts it.
That is what I mean by intelligence amplification. The interaction extends the engineer’s ability to explore the problem. The contribution becomes useful when the engineer can turn it into a discriminating question: what observation would help us tell this explanation apart from the alternatives?
The team now has a possible direction for investigation, with the cause of the failure still unresolved. Its value depends on whether it makes the next experiment more informative. A better question can be a meaningful contribution long before there is a solution, particularly when it challenges an assumption the team has been carrying forward.
There is evidence of useful amplification in specific settings. In a study published in The Quarterly Journal of Economics in 2025, Erik Brynjolfsson, Danielle Li, and Lindsey Raymond examined the introduction of an AI assistant across 5,172 customer-support agents. Access to the assistant increased issues resolved per hour by 15% on average, with larger benefits for less experienced and lower-skilled workers.
That result belongs to the workflow studied. It is not a forecast for semiconductor yield or a promise about engineering productivity. What matters here is that the researchers evaluated a concrete work outcome. The practical value could be measured without resolving whether the underlying model possessed human-like understanding.
That is the approach I would carry into an engineering organization. Define a useful outcome before evaluating the tool. In an investigation, that could mean reaching a well-supported test plan sooner. The assessment should include the time spent checking the answer, especially when an attractive explanation could send the team in the wrong direction.
The most important boundary is between a suggestion and something the organization is prepared to act on. NIST identifies confidently presented false content as a generative-AI risk and notes that even the apparent logic or citations supporting an answer can be fabricated. Asking an AI to explain itself does not, on its own, verify the explanation.
During exploration, give the assistant a clear account of the observations and ask it to expose assumptions. An unfamiliar explanation can be worth examining without being ready for acceptance. Keeping it visibly provisional makes it easier for another engineer to challenge it without having to overturn a premature conclusion.
As the work moves toward a consequential decision, check the original evidence and whether the comparison is valid. In the packaging example, a mechanism reported elsewhere would still need to fit the actual materials and process conditions. A proposed production change should pass through the team’s established validation and approval process.
For a manager, a useful review question is: “What do we understand now that we did not understand before, and what supports that change?” A conversation that exposes a critical unknown may deserve more attention than a long report that confidently restates the initial assumption.
This also changes what should survive the conversation. Preserve the useful question with its evidence and unresolved assumptions, so someone else can evaluate it. A colleague should be able to see why the investigation changed direction without reconstructing the entire exchange.
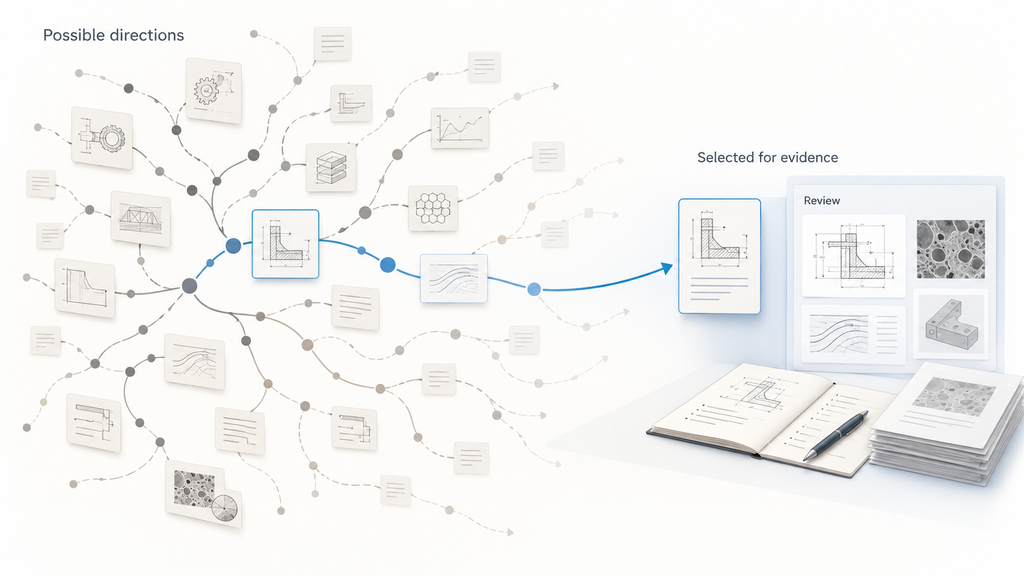
Suppose an engineer can now generate ten plausible directions in the time previously needed to develop two. That is an expansion of possibility. Laboratory capacity and the hours available for careful review have not necessarily expanded with it.
Under those conditions, selecting the right work becomes more important. Someone has to decide which uncertainty deserves an experiment and which apparently promising idea has too little relevance to pursue. More available analysis makes the quality of that choice increasingly consequential.
This is where the debate about intelligence connects to an organizational question. We should keep investigating what these systems understand and testing their limits. At the same time, we can use the capabilities already demonstrated, with the scrutiny appropriate to the decision.
I am less interested in awarding a machine the title of intelligent than in understanding what becomes possible when people work with it. The opportunity is to extend our reach while remaining clear about what we actually know.
As the capacity to explore grows, the next question becomes what deserves our attention.